Overview
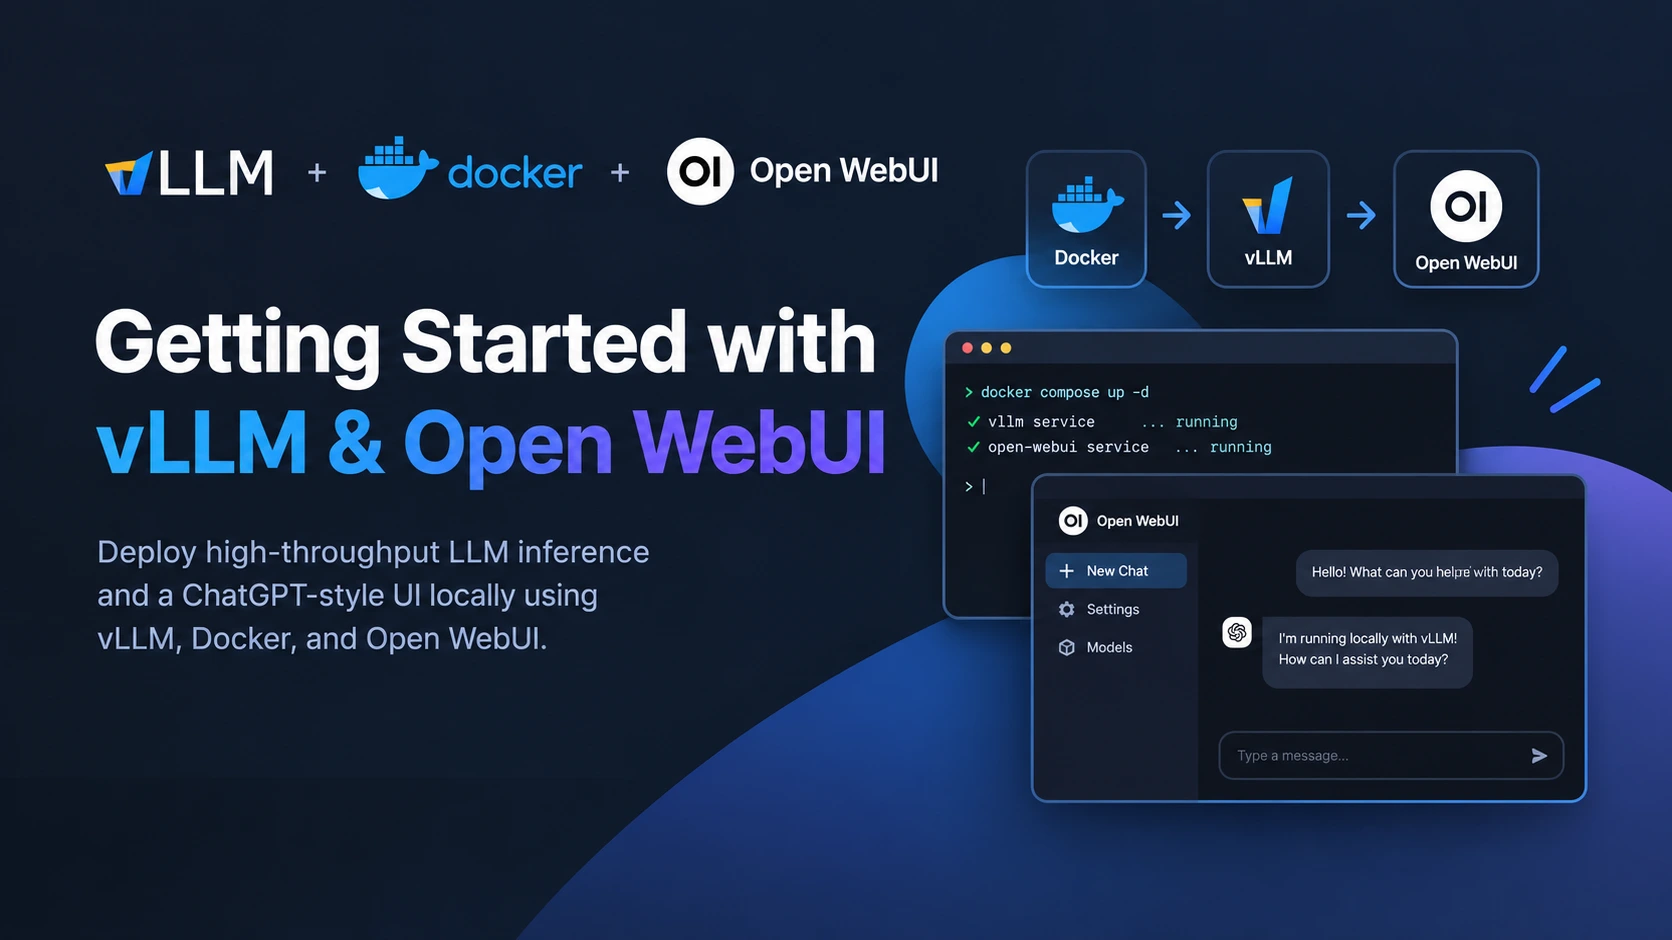
In this hands-on codelab, learn how to deploy and run Large Language Models (LLMs) locally using vLLM and Open WebUI. Explore how vLLM enables high-throughput, low-latency LLM inference through efficient model serving, while Open WebUI provides an intuitive, ChatGPT-style interface for interacting with locally hosted models.
Starting with the fundamentals, you’ll learn how to set up the environment using Docker, configure vLLM as an inference server, and connect it to Open WebUI to build a fully functional local AI chat experience. The session will cover model deployment, API integration, containerized workflows, and practical considerations for running LLMs on your own infrastructure.
By the end of the session, you’ll understand how to serve open-source LLMs, interact with them through a web-based interface, and build a foundation for experimenting with local AI applications. Whether you’re an AI developer, software engineer, or enthusiast exploring self-hosted AI, you’ll gain practical knowledge to get started with efficient LLM inference and local AI deployment.
Join Stepwik
Build and share what you know
Create interactive labs and courses that help developers learn faster - then publish them to your network.
- Create labs
- Share with learners
- Grow your audience